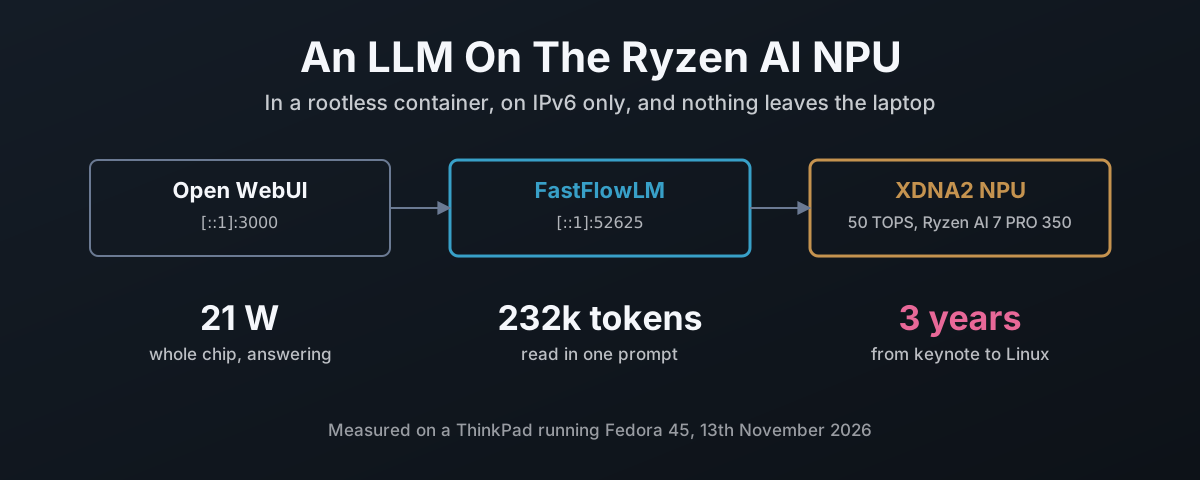
Running An LLM On The Ryzen AI NPU, In A Container
The NPU in a Ryzen AI laptop is 50 TOPS that sits idle on most Linux installs. This walks through building AMD’s amdxdna driver and keeping only the kernel module on the host, building FastFlowLM with AMD’s XRT runtime into a rootless podman container matched to that driver, binding everything to IPv6 loopback and starting it at boot with Quadlet. Then what it does: nine models benchmarked, a 232,000-token context test, Whisper speech-to-text at ten times real time, Open WebUI and the 7,000 hidden tokens it was adding to every message, and the speed and energy of the NPU measured against llama.cpp on the Radeon 860M iGPU. Last, the timeline: three years from AMD announcing Ryzen AI to a language model on its NPU under Linux, delivered by a project AMD did not start, while the effort went to Copilot+ on the Fisher-Price OS (Windows) instead of the data centre and the Linux tooling AI professionals actually use.